Benchmarks / Model
Claude Opus 4.7
Results for Claude Opus 4.7 by Anthropic across JumalAIta Intelligence benchmarks, with the configuration and run details of every evaluation.
01 / Results
Benchmark results
| Benchmark | Version | Rank | Evaluation | Configuration | Status |
|---|---|---|---|---|---|
| Creative Reimplementation Benchmark | v1.0 | 3 | Expert-ranked | Single shot · High | Final |
02 / Run details
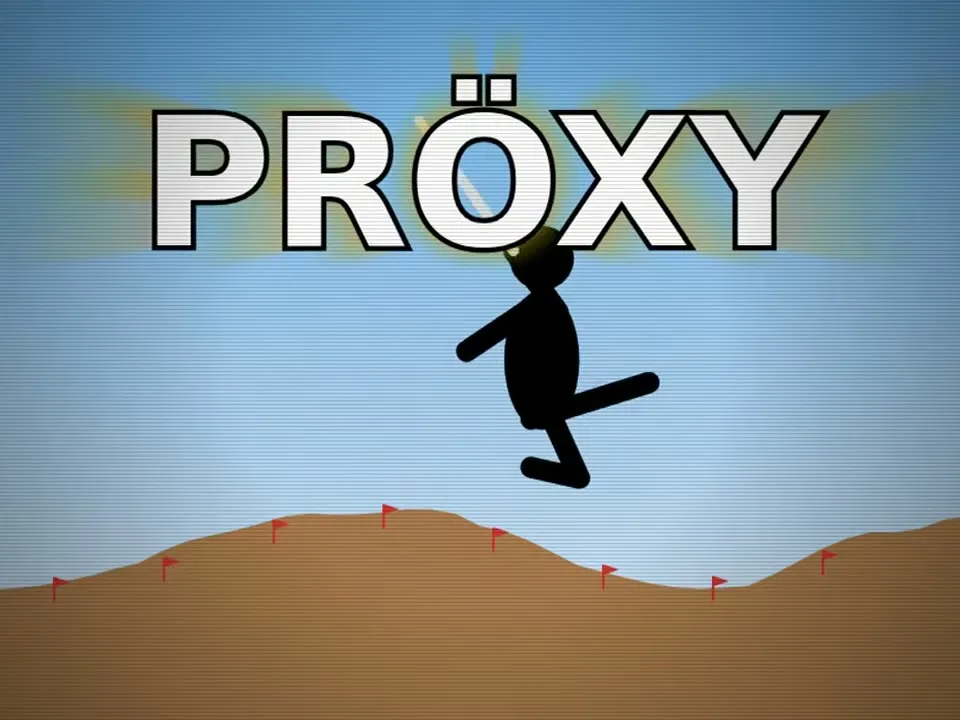
Creative Reimplementation Benchmark
- Benchmark version
- v1.0
- Generation
- Single shot
- Reasoning effort
- High
- Harness
- Not yet published
- Evaluated on
- Not yet published
- Run time
- Not yet published
- Cost
- Not yet published
- Tokens
- Not yet published
- Evaluators
- The original authors of the reference demo (members of Jumalauta)
- Recording length
- 2 min 55 s
- Recording published
- 2026-09-06
Evaluators' notes
- Rank 3
Claude Opus 4.7
According to the original authors, the Claude Opus 4.7 version looks noticeably rougher than the two newer entries.